Task-specific collection
Protocols built around a defined learning or evaluation gap.
Real-world data for Physical AI
AVIROB designs and operates custom egocentric data-collection programs across European manufacturing, warehousing, assembly and logistics environments.
750+
Potential participants through operating partners
4
Core operational domains
Custom
Protocols designed around each model requirement
EU
Permissioned real-world collection network
Program design
We work with robotics and AI teams to define the task, environment, sensing setup, annotation ontology and delivery schema before collection begins. Programs can include routine execution, task variation, failure, correction and recovery.
Protocols built around a defined learning or evaluation gap.
Manufacturing, warehousing, assembly and logistics workflows.
RGB, depth, IMU and audio depending on the program and hardware.
Temporal segments, annotations, metadata, provenance and QC documentation.
What we collect
Human experience, captured for Physical AI. We capture high-quality egocentric demonstrations of people performing real-world tasks across industrial and operational environments — turning human interaction with the physical world into structured data for robot learning.
Real production workflows and human-machine interaction.
Picking, sorting, packing and material handling.
Dexterous manipulation, insertion, fastening and multi-step assembly.
Natural human interaction with tools, components and equipment.
Measurement, verification and quality-control workflows.
Material movement, handling and fulfillment operations.
See the data
A close look at the visual quality, viewpoint and annotation detail we deliver from real manufacturing workflows.
Original footage and structured annotations shown side by side—from hand-object interaction to tools, machinery and task context.
How it works
A clear operating sequence connects program definition, real-world capture, structured processing and validated delivery.
Why egocentric
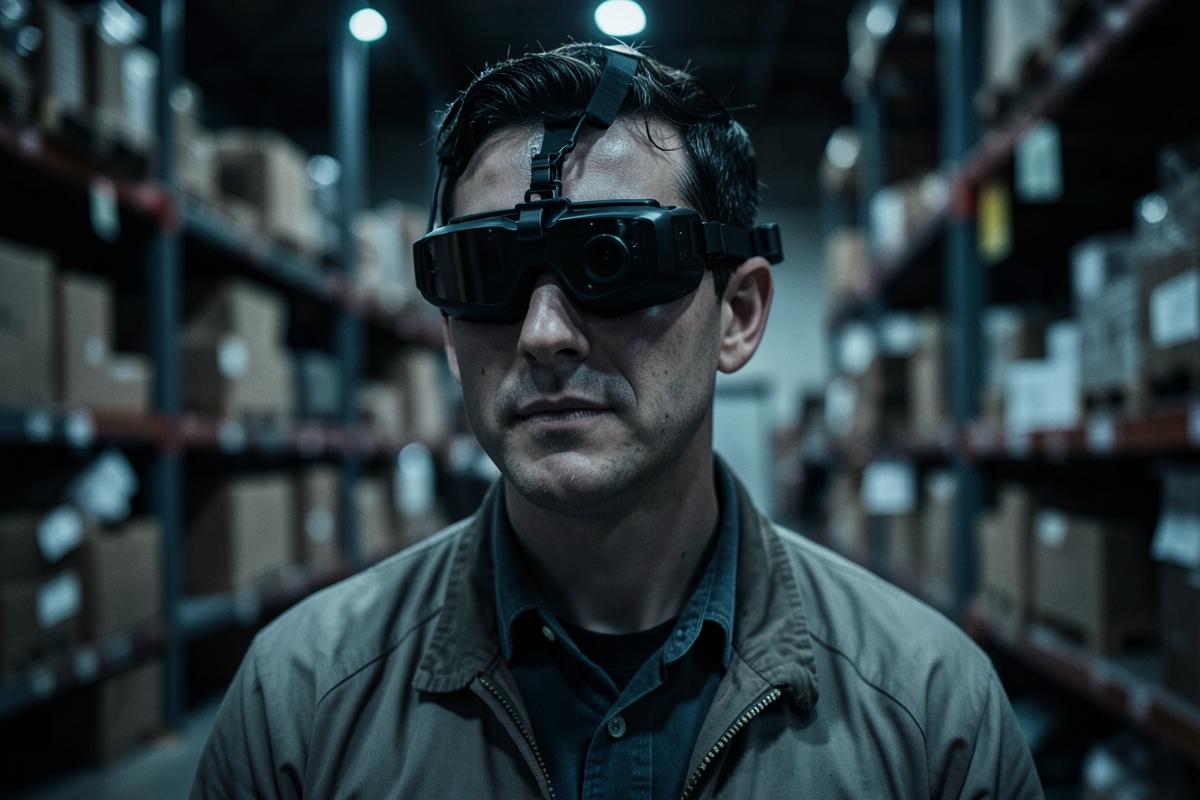
Third-person footage loses the exact thing embodied models need: the actor's viewpoint, gaze, reach and contact moments. First-person capture keeps the causal link between intention and action intact.
Pilot output
Tell us the task, the environment and the model you're training. We'll design the capture protocol and return a pilot batch.
Request a pilot